The open pipeline framework for agents and data teams
Safely build pipelines for agentic scale with built-in data quality, validation and governance.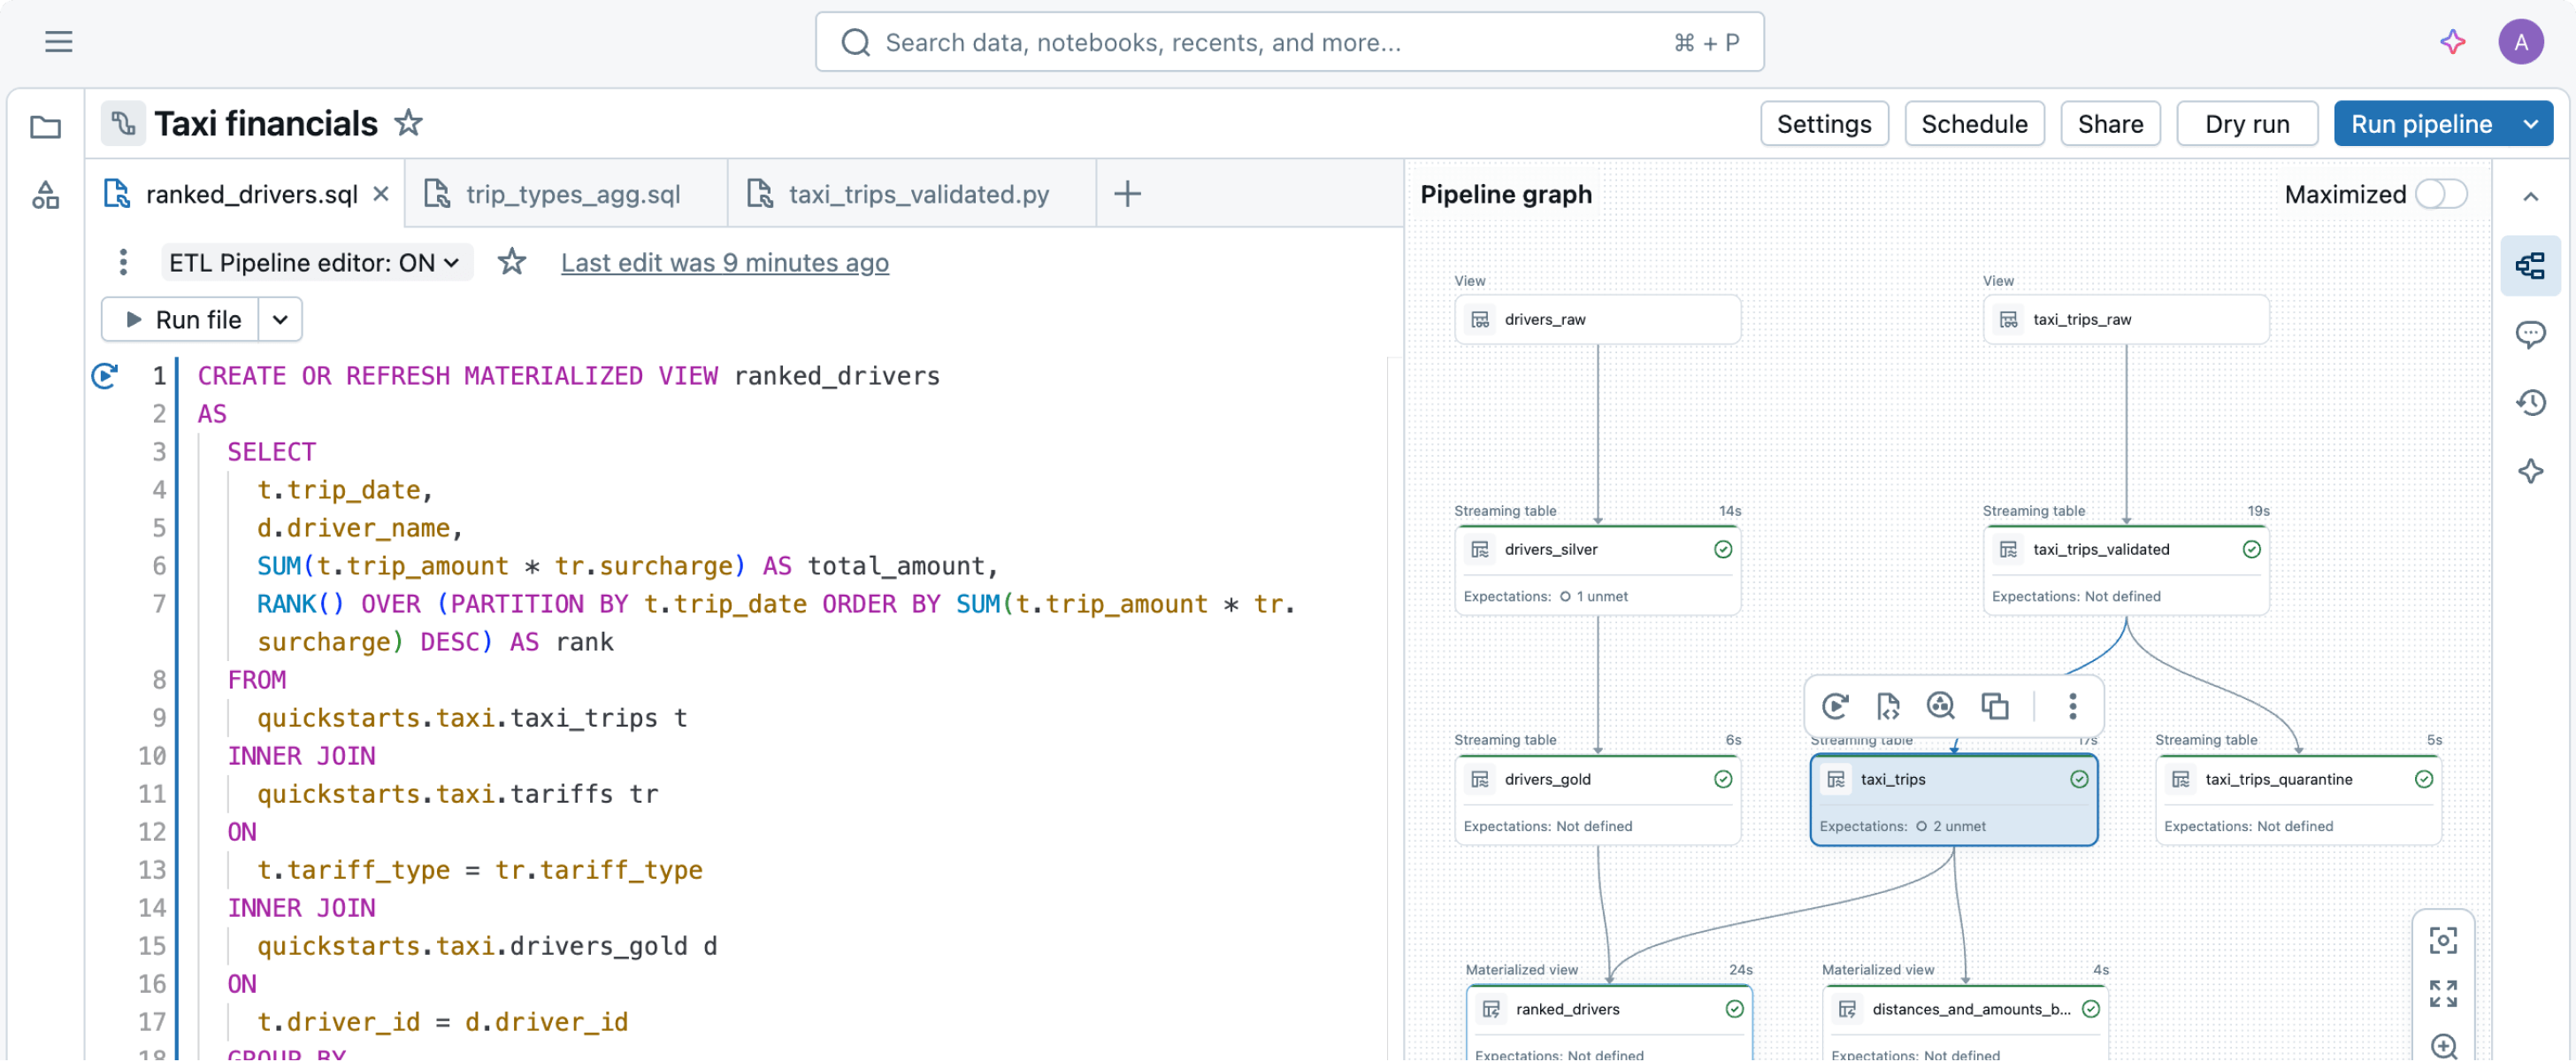
TOP TEAMS SUCCEED WITH INTELLIGENT DATA PIPELINES
Build and run pipelines at agentic scale with confidence
Empower data teams and AI agents with open standards, automated quality checks and enterprise-grade governance.
Open standards
The universal open standard for data pipelines. Unify batch and streaming, as well as SQL and Python, on Apache Spark™ — providing a portable foundation for data teams and AI agents to generate robust production code.

Built for agents
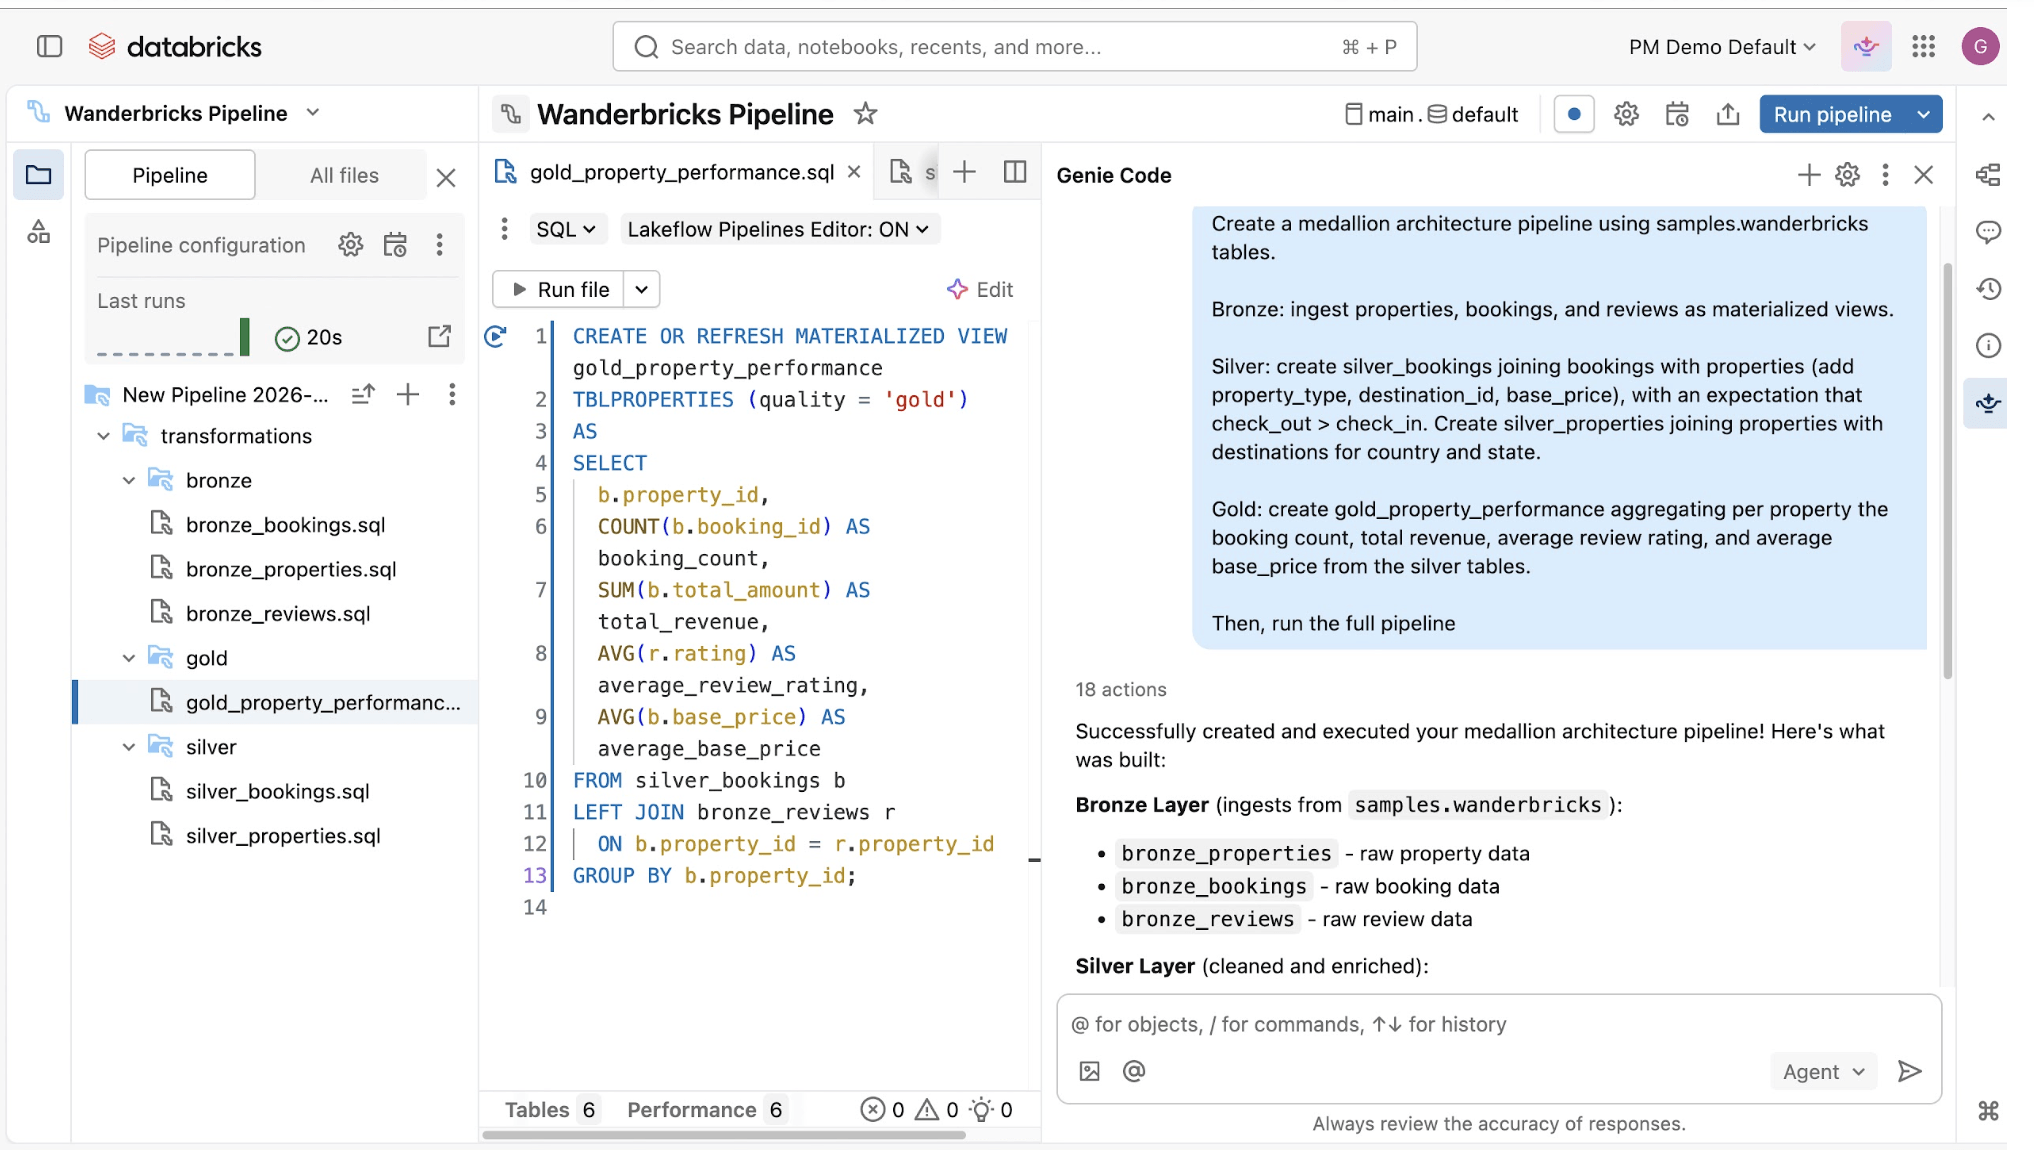
The native framework for coding agents. Agents declare target data outcomes. Apache Spark™ Declarative Pipelines (SDP) automatically resolves dependency graphs, runs compiler dry runs and enforces quality rules before pipelines run.

Governed execution
Safe, autonomous pipeline execution. Unity Catalog enforces strict catalog boundaries and security, while SDP handles state management, error recovery and incremental processing behind the scenes.
Built to standardize pipeline development for agents and humans
Standardize pipeline development with agent-ready authoring, automated pattern handling and one framework for all teams.Author, validate and iterate declaratively using natural language via Genie Code — or via your coding agent of choice.
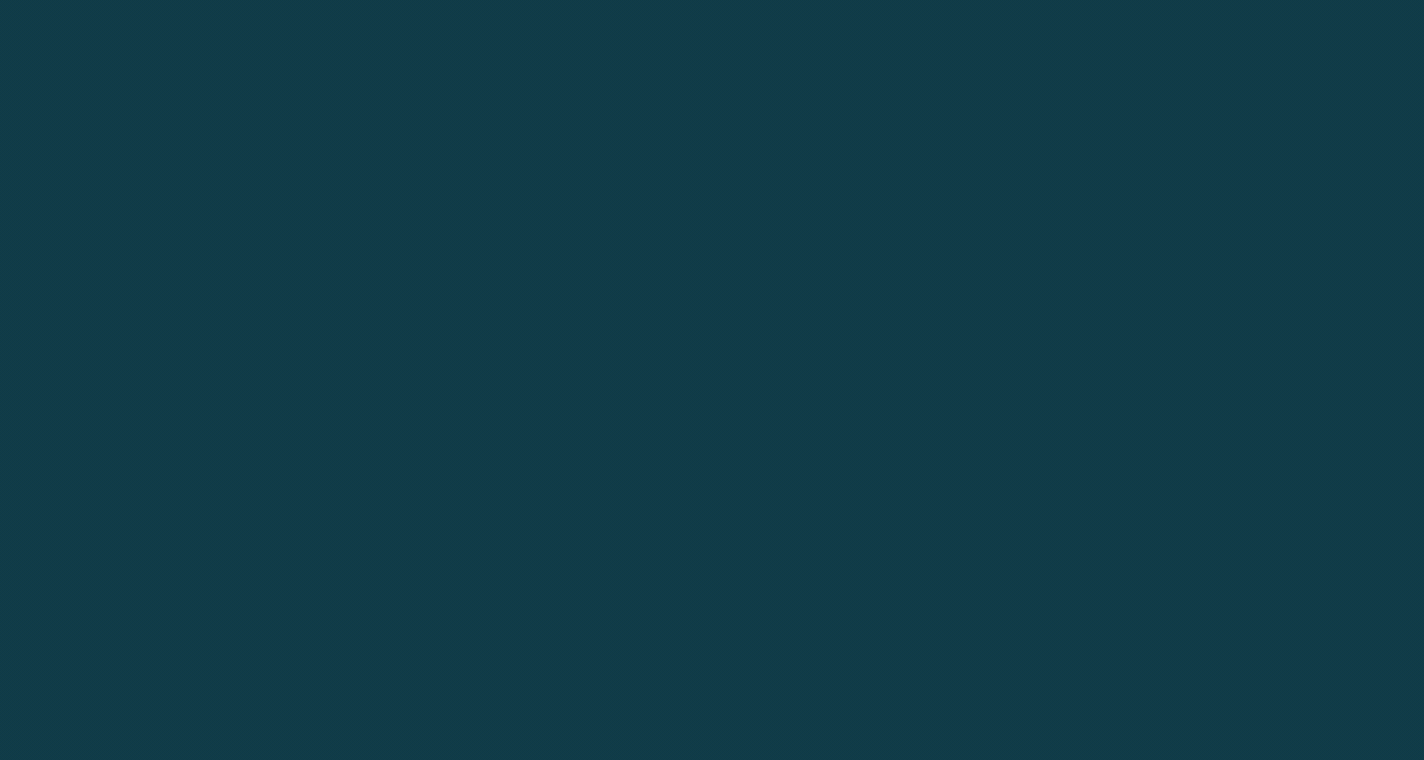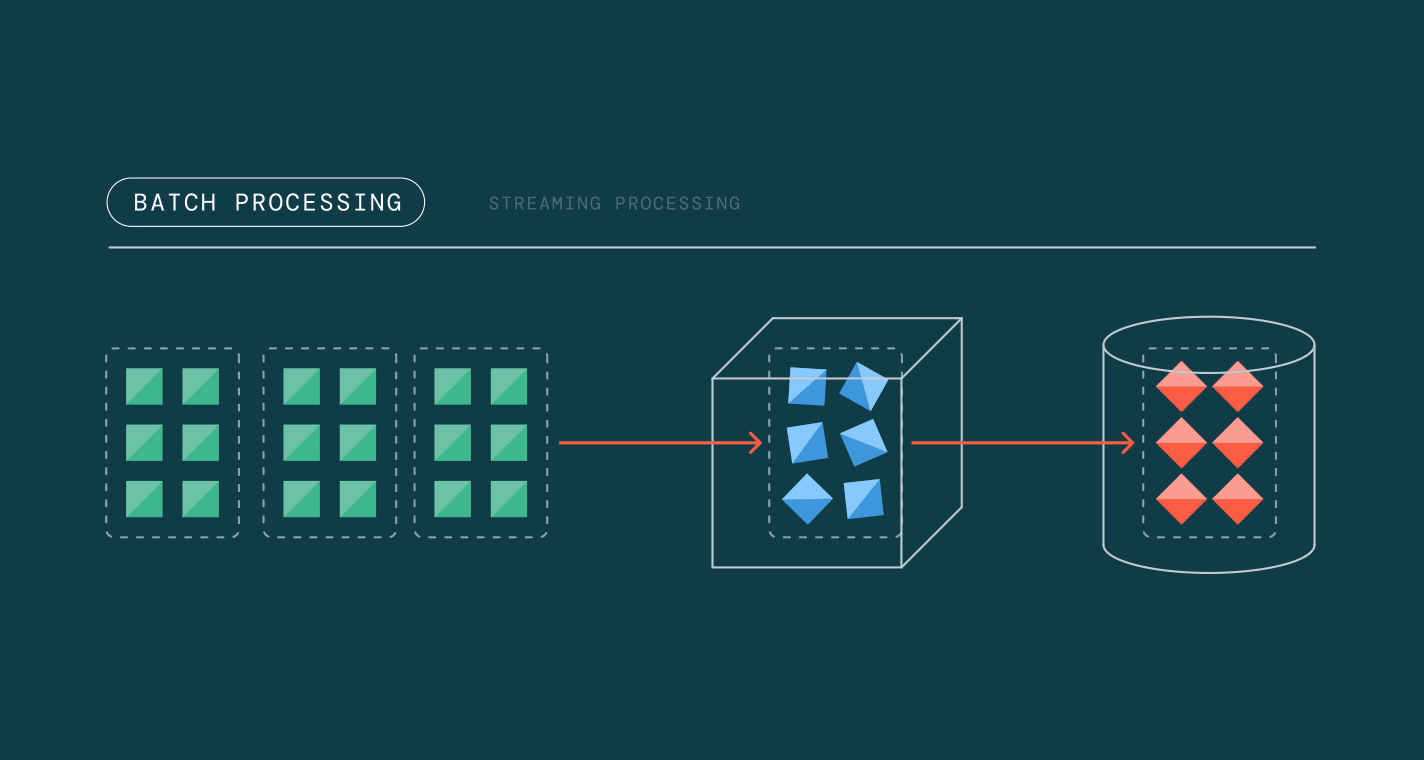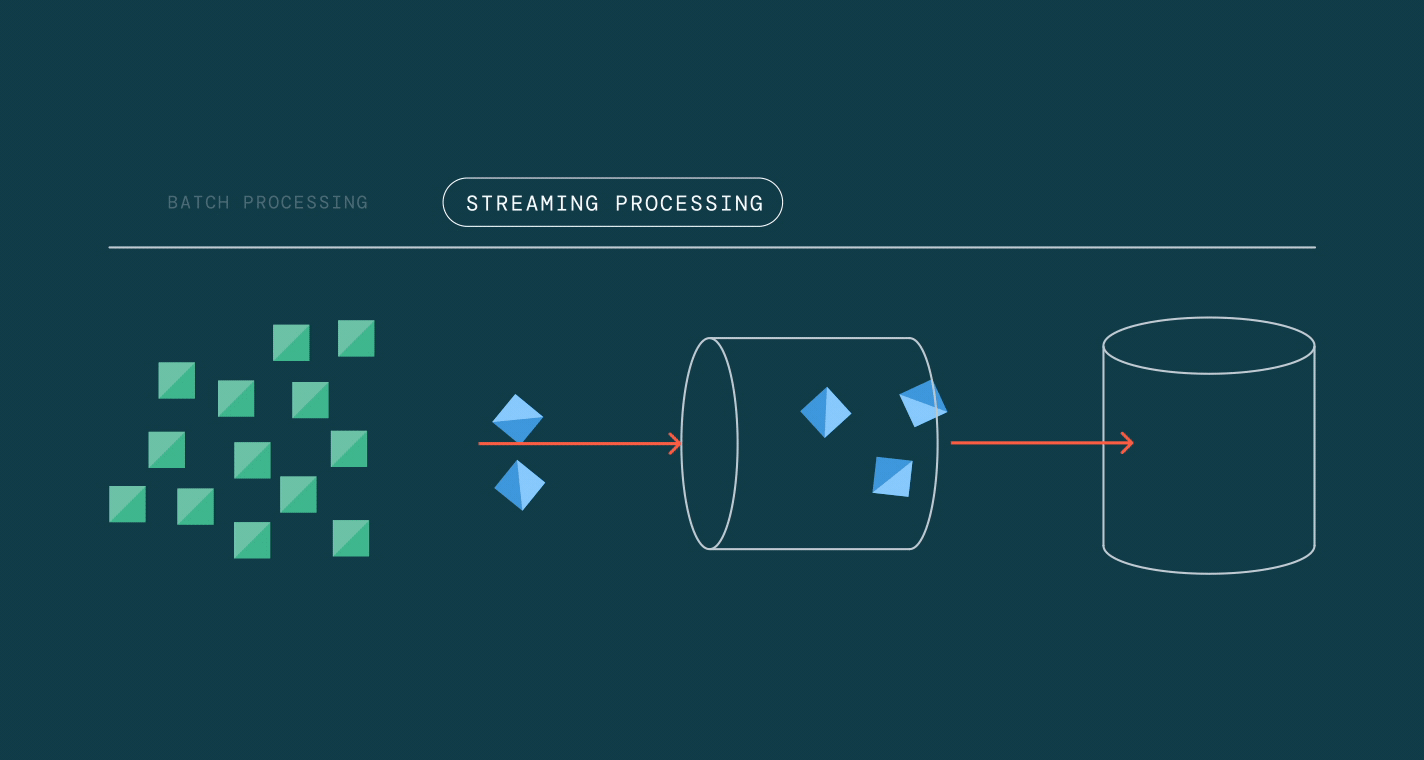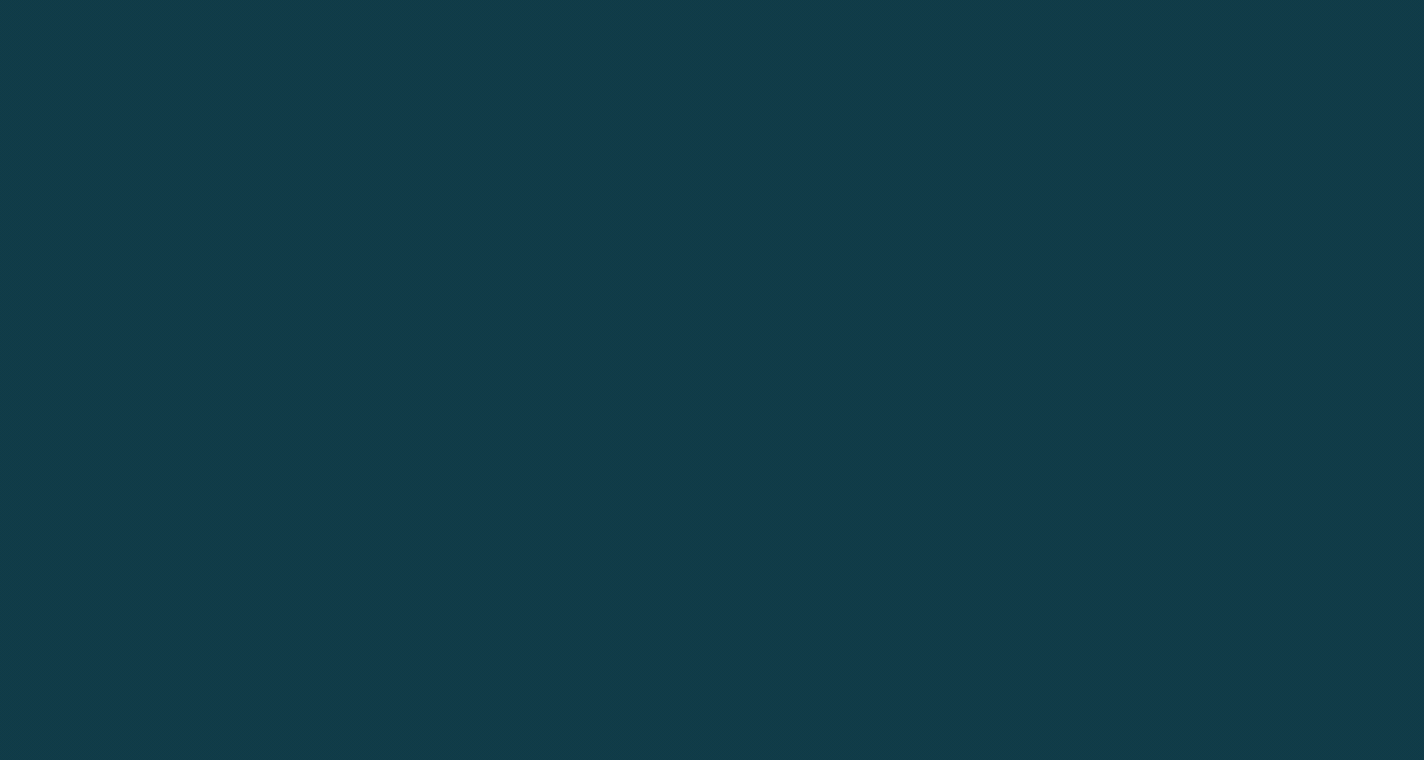
Leveraging Spark’s unified API for batch and stream processing, SDP allows you to easily toggle between processing modes.
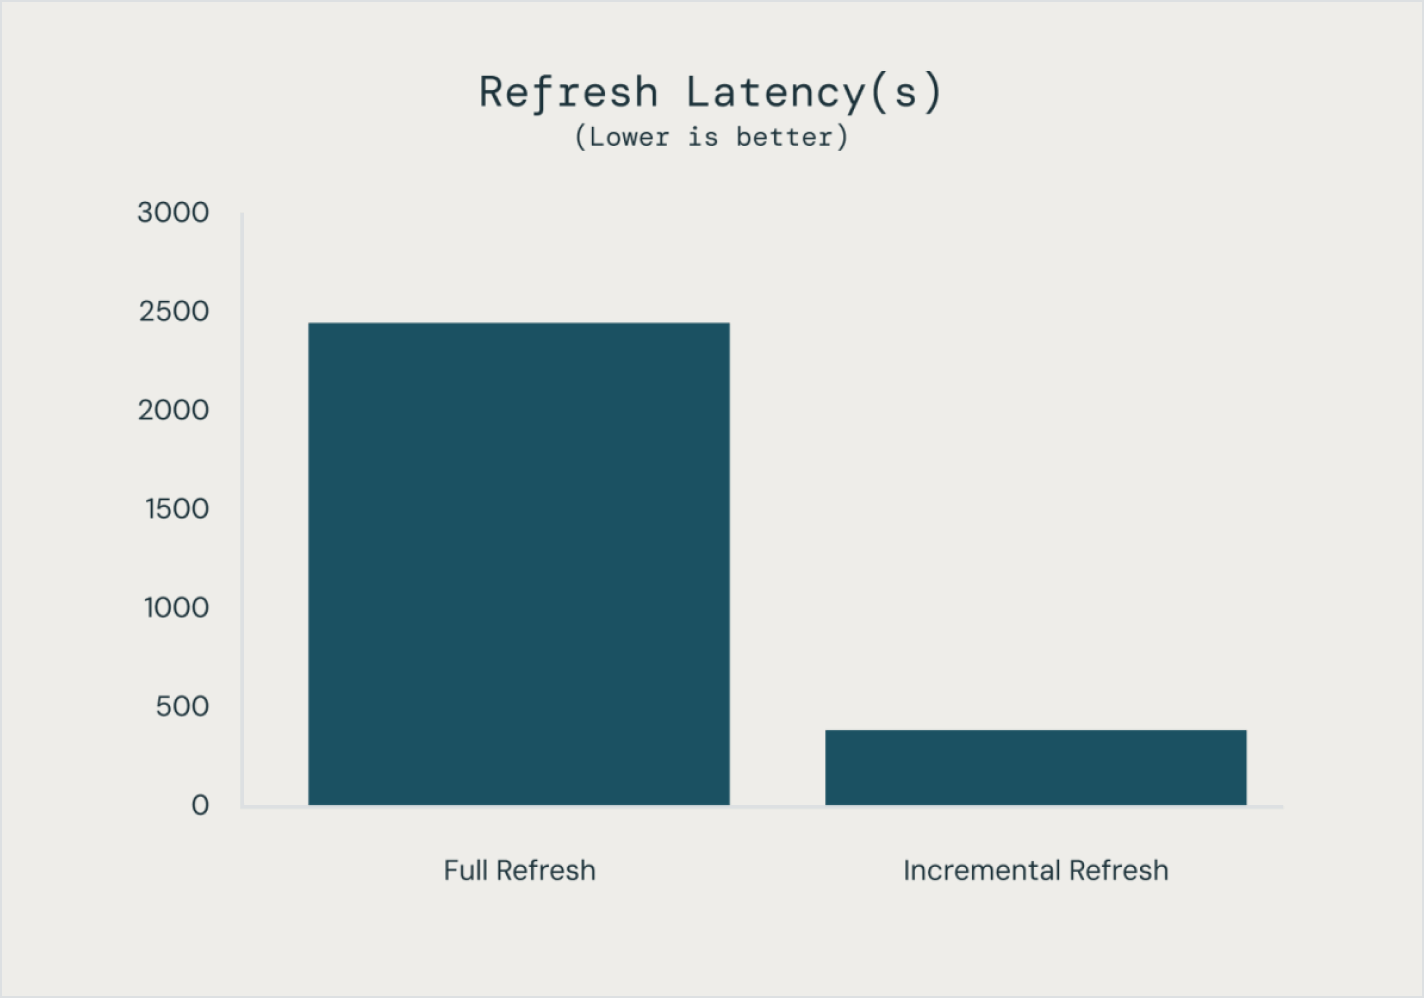
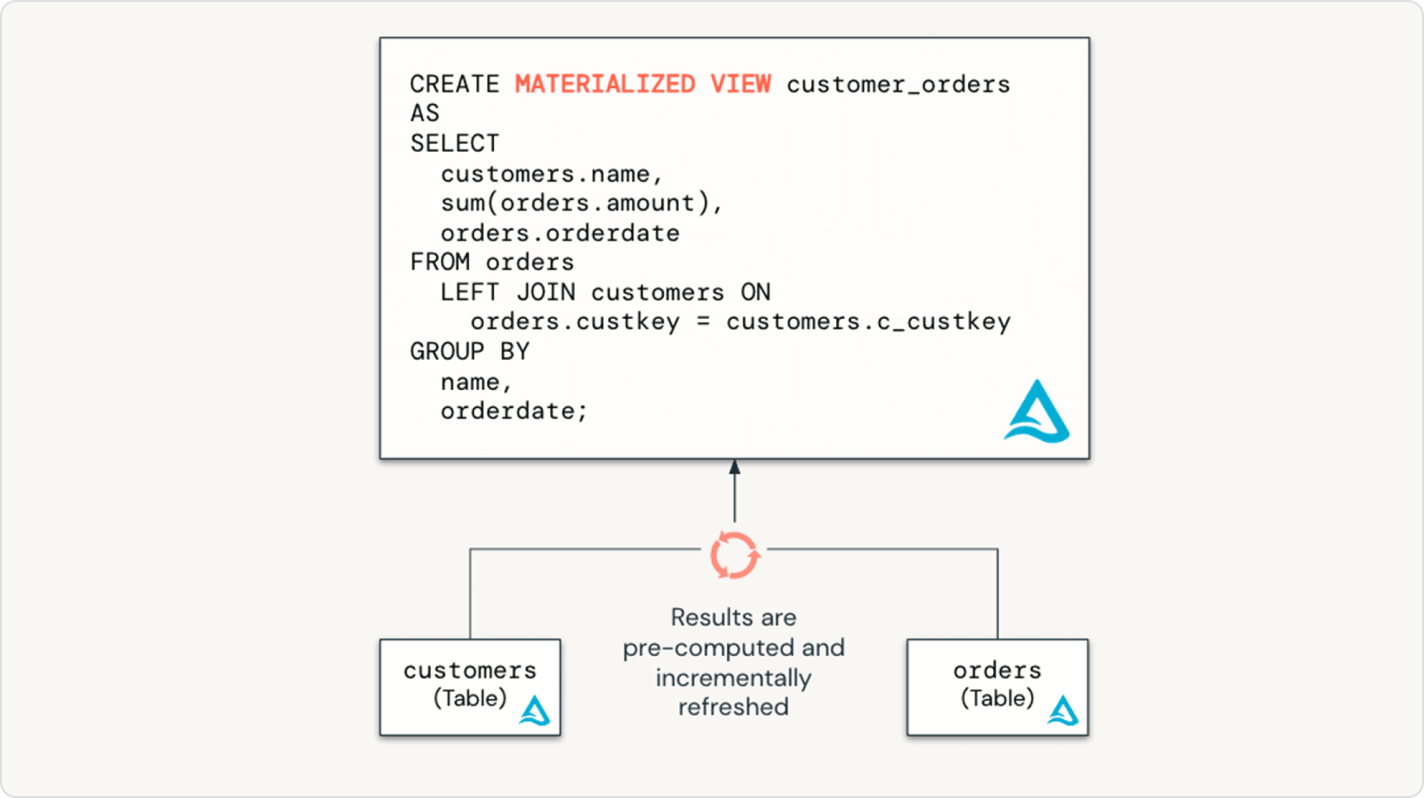
SDP makes it easy to optimize pipeline performance by declaring an entire incremental data pipeline with tables and materialized views.
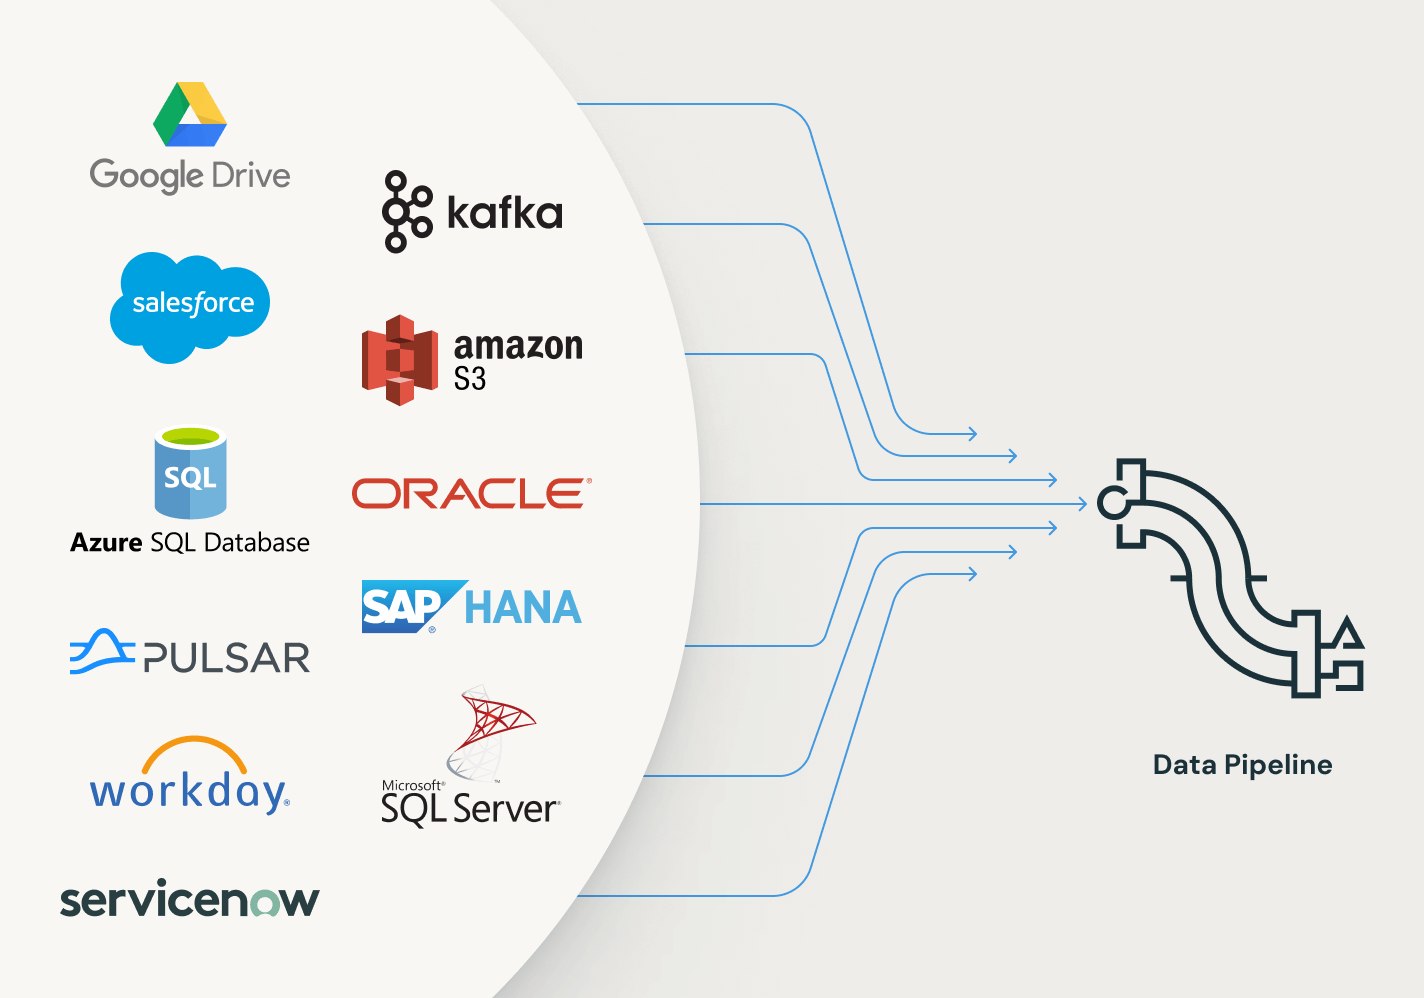
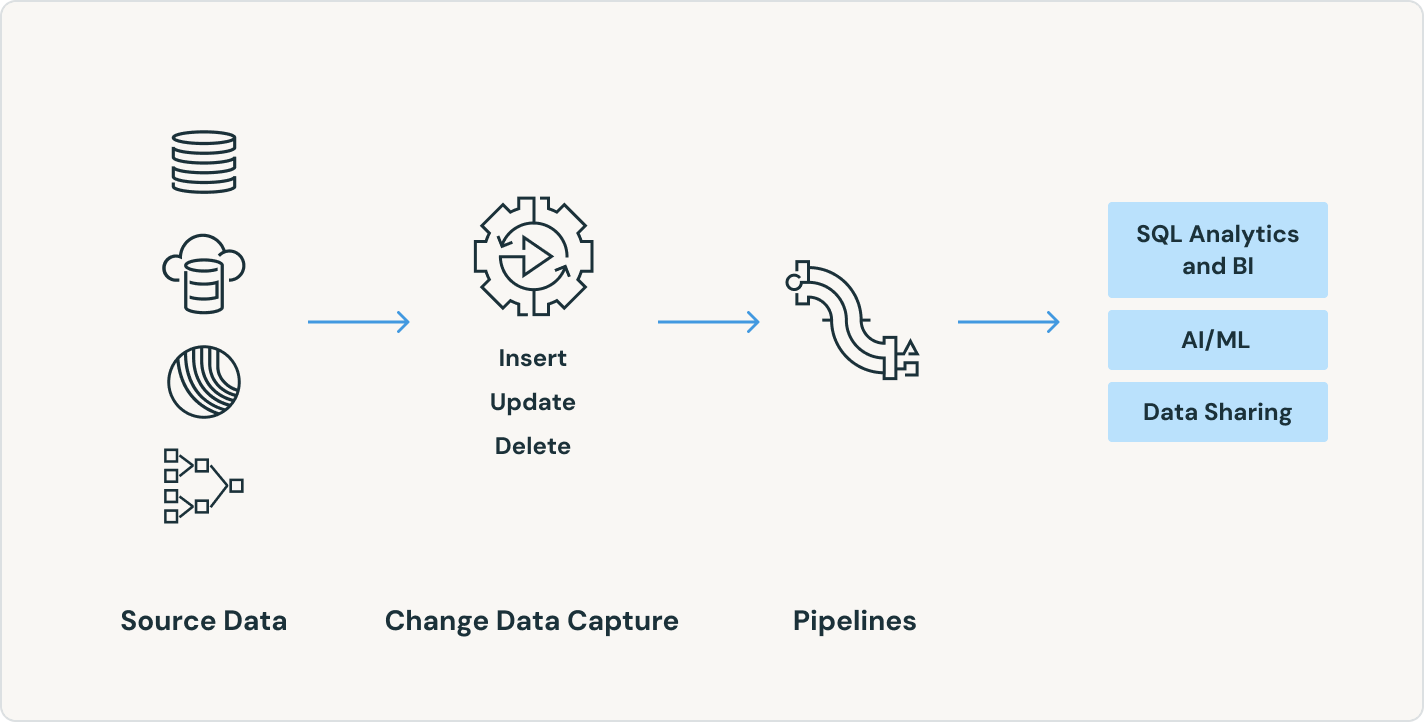
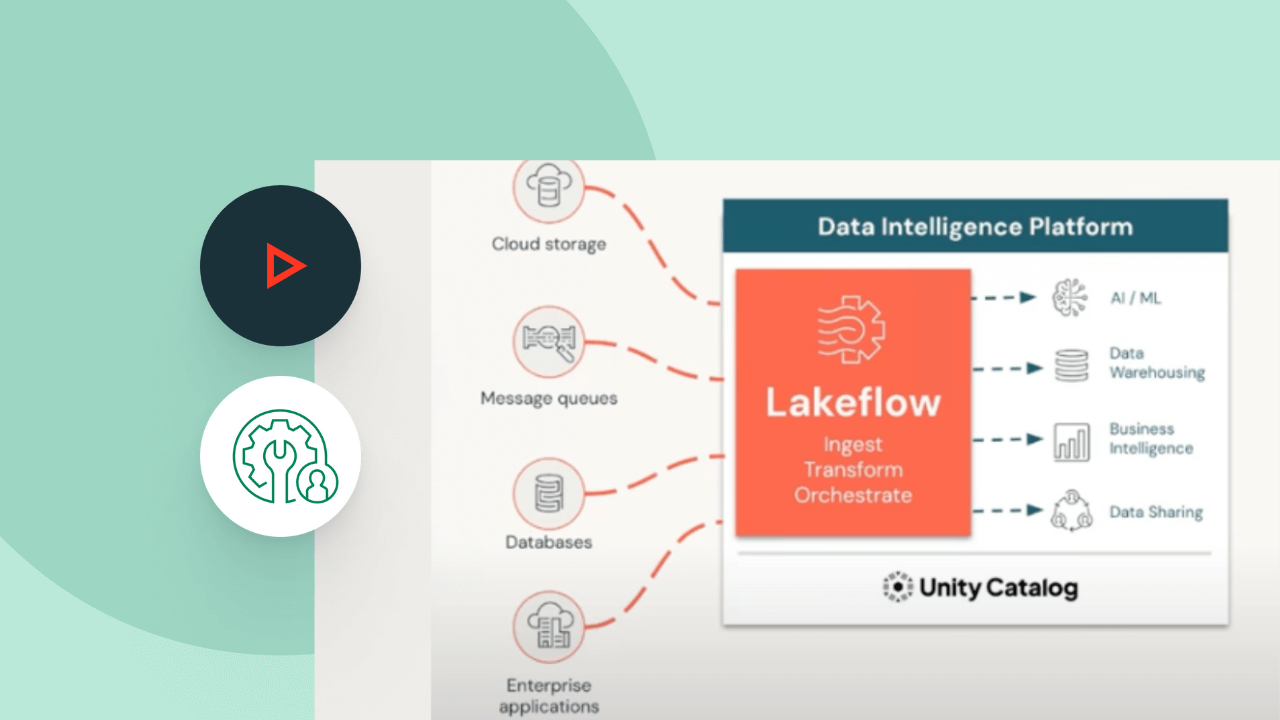
SDP supports a broad ecosystem of sources and sinks. Load data from any source — including cloud storage, message buses, change data feeds, databases and enterprise apps.
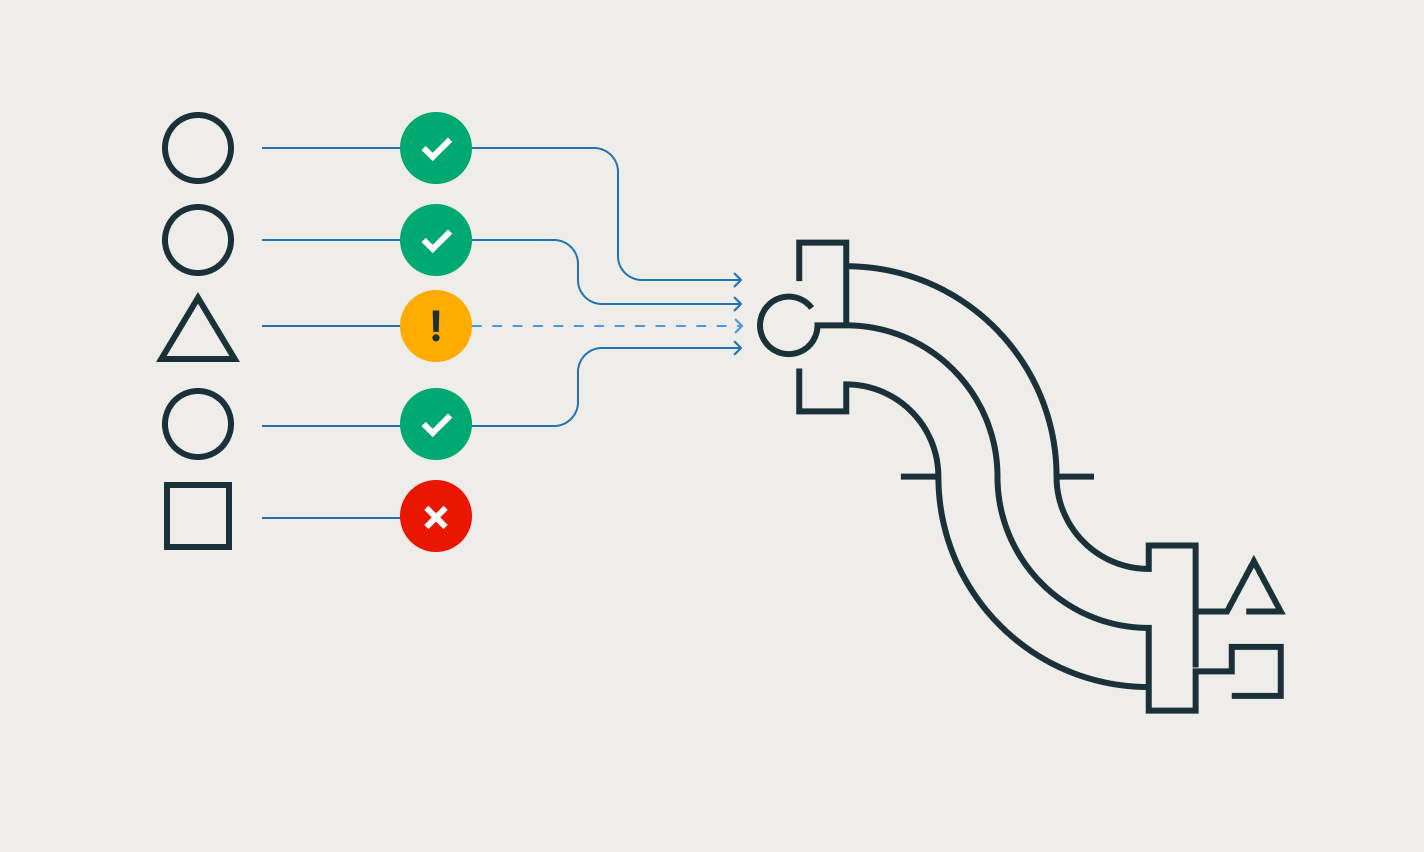
Expectations allow you to guarantee that data arriving in tables meets data quality requirements and provides insights into data quality with each pipeline update.
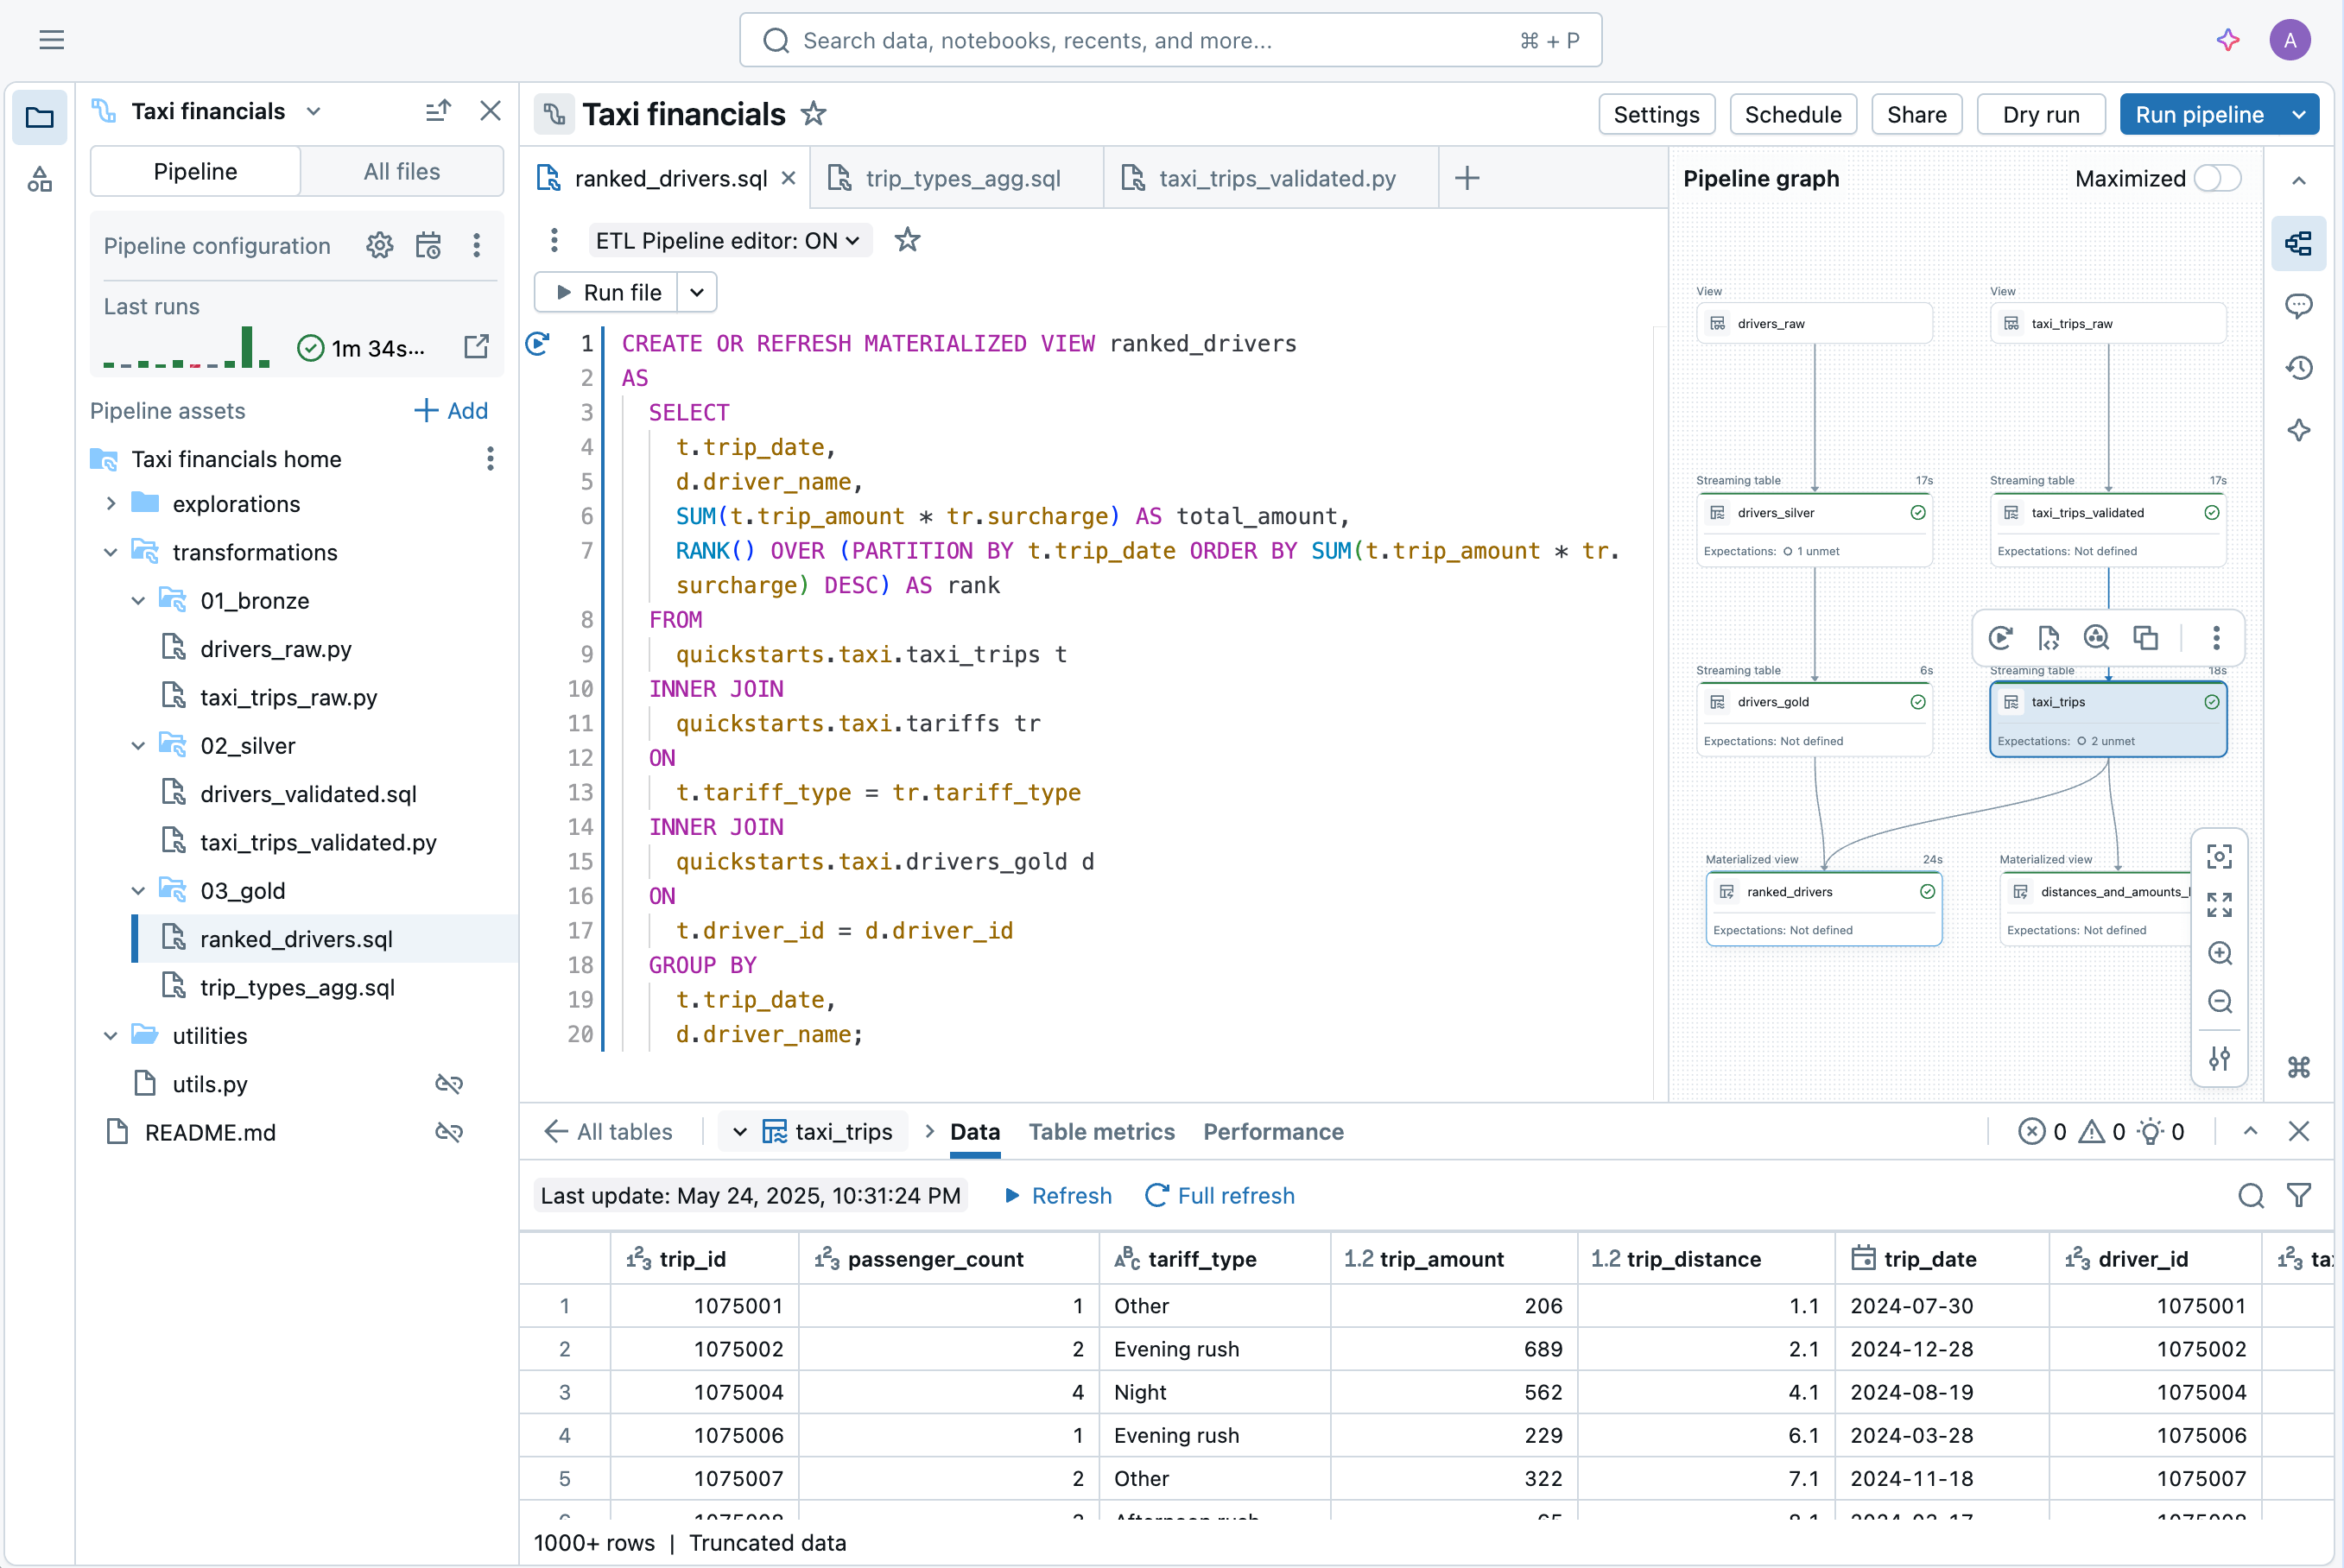
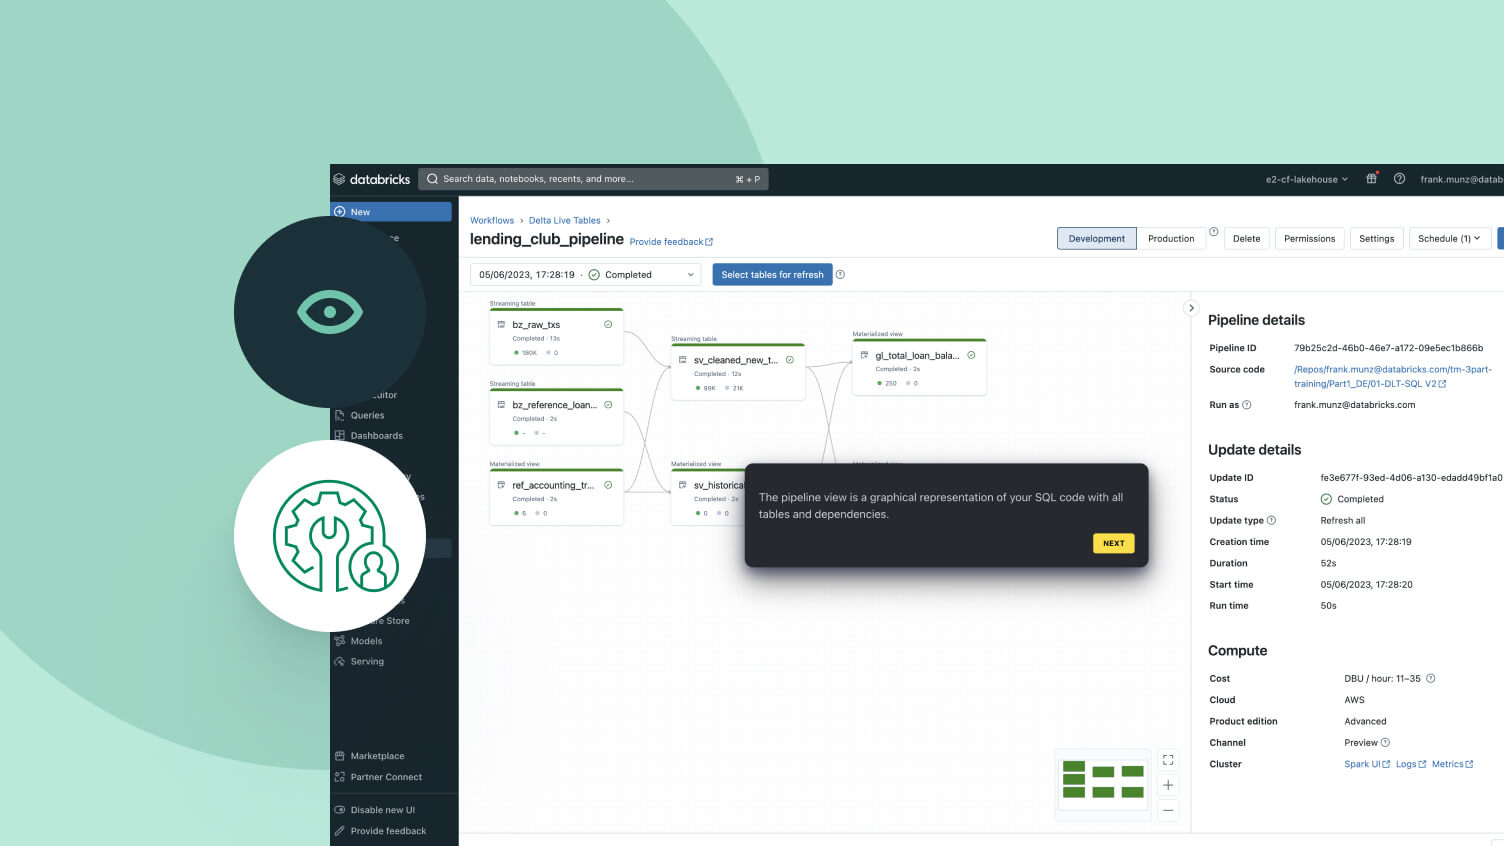
Develop pipelines in the Lakeflow pipeline editor — a native IDE for data engineering — without any context switching. See the DAG, data preview and execution insights in one UI. Develop code easily with autocomplete, in-line errors and diagnostics.
More features
Streamline your data pipelines

Make sources, transformations and destinations simple
Declarative programming means you get to harness the power of ETL on the Databricks Platform with just a few lines of intent.
Usage-based pricing keeps spending in check
Only pay for the products you use at per-second granularity.Discover more
Explore other integrated, intelligent offerings on the Databricks Data + AI Platform.
Genie Code
Your autonomous AI partner for data work.

Lakeflow Connect
Efficient data ingestion connectors from any source and native integration with the Databricks Data + AI Platform unlock easy access to analytics and AI, with unified governance.

Lakeflow Jobs
Easily define, manage and monitor multitask workflows for ETL, analytics and machine learning pipelines. With a wide range of supported task types, deep observability capabilities and high reliability, your data teams are empowered to better automate and orchestrate any pipeline and become more productive.

Lakehouse Storage
Unify the data in your lakehouse, across all formats and types, for all your analytics and AI workloads.

Unity Catalog
Seamlessly govern all your data assets with the industry’s only unified and open governance solution for data and AI, built into the Databricks Data + AI Platform.

Document Intelligence
Parse, extract and classify enterprise documents at scale with built-in governance for agentic AI.

The Databricks Data + AI Platform
Find out how the Databricks Data + AI Platform enables your data and AI workloads.
Take the next step
Spark Declarative Pipelines FAQ
Spark Declarative Pipelines (SDP) is an open framework that simplifies batch and streaming data engineering on Apache Spark. By allowing data teams and coding agents to declare target data states instead of writing procedural code, SDP automatically resolves dependencies, enforces data quality expectations and handles incremental state management.
Ready to become a data + AI company?
Take the first steps in your transformation