Announcing the Public Preview of Predictive I/O for Updates
Up to 10x Performance Gains for MERGE, UPDATE, and DELETE
by Piyush Revuri, Bart Samwel, Ala Luszczak, Lars Kroll, Polo-François Poli, Frank Munz and Himanshu Raja
Previously, we’ve shown you how a new technology called Predictive I/O could improve selective reads by up to 35x for CDW customers without any knobs. Today, we are excited to announce the public preview of another innovative leap, Predictive I/O for Updates, providing you with up to 10x faster MERGE, UPDATE, and DELETE query performance.
Databricks customers process over 1 exabyte of data daily, with more than 50% of tables utilizing Data Manipulation Language (DML) operations like MERGE, UPDATE, and DELETE. In this blog, we explain how Predictive I/O achieved this massive performance improvement using machine learning. But, if you want to skip to the good part and opt-in your tables to Predictive I/O for Updates, refer to our documentation.
Challenges with updating data lakes
Today, when users run a MERGE, UPDATE, or DELETE operation in the Lakehouse, the queries are processed by the query engine in the following manner:
- Find the files that contain the rows needing modification.
- Copy and rewrite all unmodified rows to a new file while filtering out deleted rows and adding updated ones.
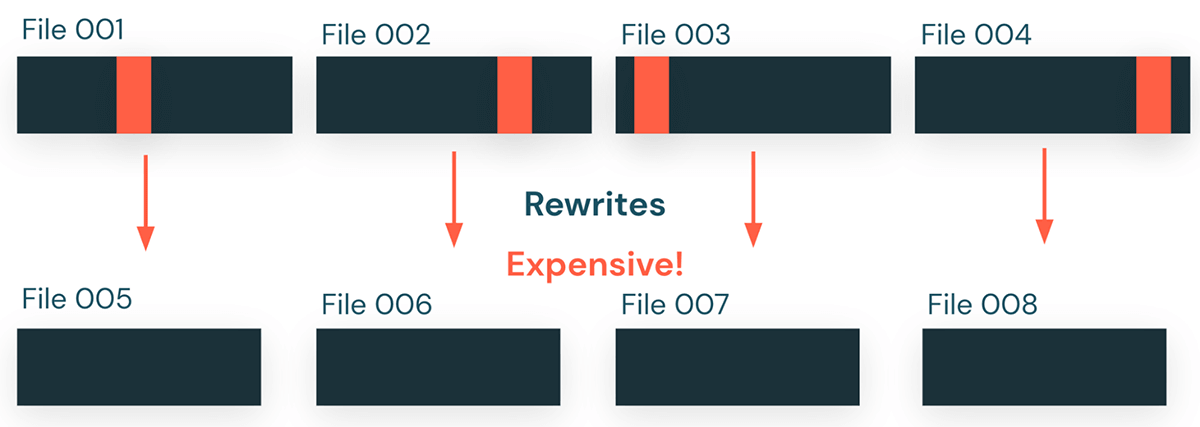
This process, especially the rewrite step, can get particularly expensive when operations make small updates distributed across many files in the table. For example, a single product ID gets updated across an entire orders table. In the illustrated example below, a table is stored as four files with a million rows each, and a user runs an UPDATE query against this table, only updating a single row in each file. Without Predictive I/O, the update query rewrites all four files, copying all four million unmodified rows to a new file to update four rows in the table. This unnecessary rewriting of old data can become expensive and slow for medium to large tables.
What is Predictive I/O for Updates?
To address these challenges, we are introducing Predictive I/O for Updates.
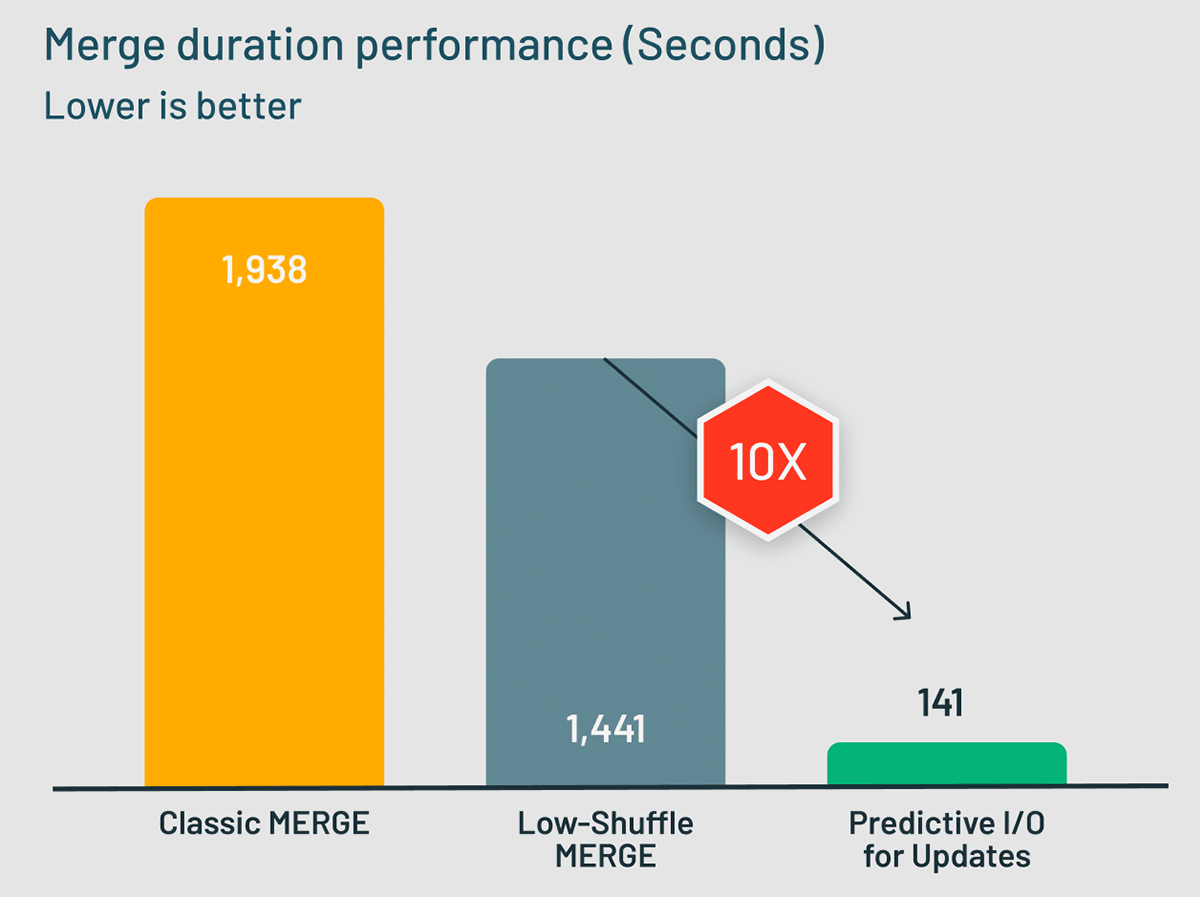
Last year, we announced Low-Shuffle MERGE, a Photon feature that speeds up typical MERGE workloads by 1.5x. Low-Shuffle MERGE is enabled by default for all MERGEs in Databricks Runtime 10.4+ and Databricks SQL. Now let's see how Predictive I/O for Updates stacks up against Low-Shuffle MERGE. Using a MERGE UPSERT workload that updates a 3 TB TPC-DS dataset, we measured the classic Photon MERGE implementation, Low-Shuffle MERGE, and Predictive I/O for Updates in a benchmark. The results were amazing! Predictive I/O for Updates took just over 141 seconds to complete the MERGE workload, 10x faster than Low-Shuffle MERGE, which took over 1441 seconds to complete the same operation.
How does Predictive I/O for Updates work?
Predictive I/O for Updates makes use of Deletion Vectors to track deleted rows using compressed bitmap files. Tracking deleted files, rather than removing them on write, adds some overhead when reading the table, as attaining an accurate table representation requires filtering deleted rows at read time. This is where Predictive I/O's intelligence comes into play. Predictive I/O uses various forms of learning and heuristics to intelligently apply Deletion Vectors as needed to your MERGE, UPDATE, and DELETE queries to minimize read overhead while optimizing write performance. This intelligence, paired with the optimized nature of Deletion Vector files gives you the best write performance without any compromises on read query performance.
How to get started with Predictive I/O for Updates
Are your ETL pipelines or CDC ingestion jobs taking a long time to execute? Do you have updates spread across your data? Predictive I/O can now significantly speed up those MERGE, UPDATE, and DELETE queries and is available today in public preview for Databricks SQL Pro and Serverless!
We want your feedback as part of this public preview. Check out the Predictive I/O for Updates documentation to learn how to speed up your MERGE, UPDATE, and DELETE queries.
Frequently asked questions
What is Predictive I/O for Updates?
Predictive I/O for Updates is a new capability, now in public preview, that speeds up MERGE, UPDATE, and DELETE queries by up to 10x. It follows the earlier Predictive I/O for Reads, which improved selective reads by up to 35x, but this version targets write-heavy DML operations instead. The feature is especially relevant given that Databricks customers process over 1 exabyte of data daily, with more than 50% of tables relying on DML operations like MERGE, UPDATE, and DELETE.
Why are MERGE, UPDATE, and DELETE queries slow without this feature?
These queries are slow because the query engine has to copy and rewrite every unmodified row in a file just to apply a small change. For example, updating a single row in each of four one-million-row files forces the engine to rewrite all four million rows to change only four values, which becomes expensive when updates are scattered across many files in medium to large tables.
How does Predictive I/O for Updates compare to Low-Shuffle MERGE?
In a benchmark using a MERGE UPSERT workload against a 3 TB TPC-DS dataset, Predictive I/O for Updates completed in just over 141 seconds versus 1441 seconds for Low-Shuffle MERGE, a 10x improvement. Low-Shuffle MERGE, introduced the prior year as a Photon feature, already sped up typical MERGE workloads by 1.5x and has been enabled by default in Databricks Runtime 10.4+ and Databricks SQL, so this new gain builds on top of that existing baseline.
What role do Deletion Vectors play in this speedup?
Deletion Vectors are compressed bitmap files that track which rows have been deleted instead of rewriting entire files to remove them. Because tracking deletions this way adds some overhead when reading the table, since an accurate view requires filtering out deleted rows at read time, Predictive I/O uses learning and heuristics to intelligently decide when to apply Deletion Vectors, minimizing read overhead while optimizing write performance for MERGE, UPDATE, and DELETE queries.
How can I enable Predictive I/O for Updates on my tables?
Predictive I/O for Updates is available today in public preview for Databricks SQL Pro and Serverless, and you can opt in your tables by following the Predictive I/O for Updates documentation. Databricks is also gathering customer feedback during this public preview to help refine the feature further.
Get the latest posts in your inbox
Subscribe to our blog and get the latest posts delivered to your inbox.